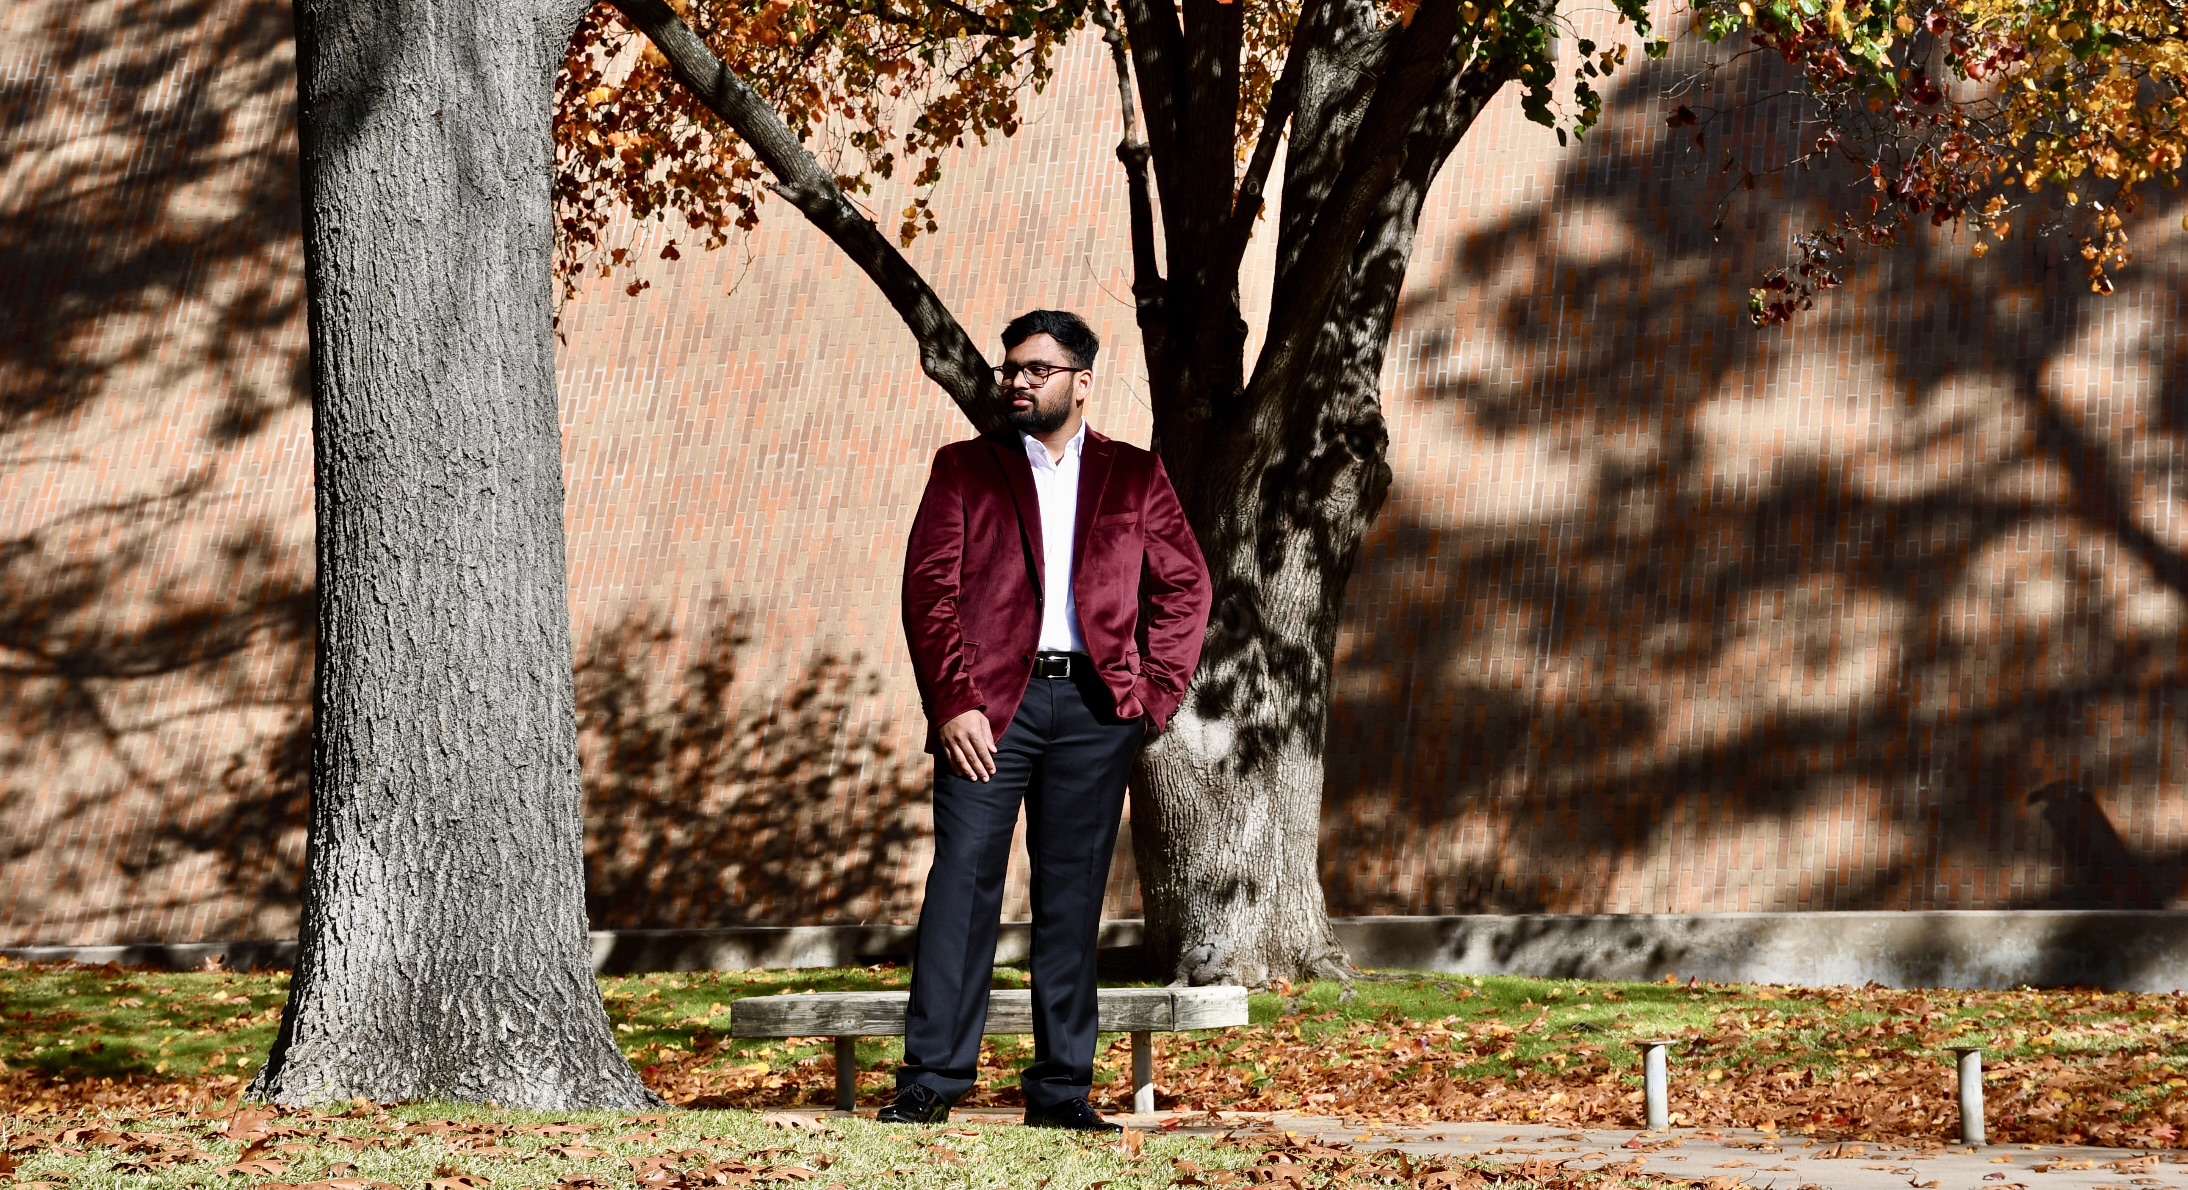
Chandra Alla in a burgundy velvet blazer, standing under an autumn tree in front of a sunlit brick wall

GenAI Engineer

AT&T AI Foundry · Dallas, TX

Agents are easy to demo and hard to trust. I build the kind that pause for approval, recover from failure, explain themselves, and ship.

From research on what a model should forget to agents that run enterprise workflows: I make AI cheaper to run and safe to rely on.

01 — About

Building memory into machines. Shipping enterprise AI.

I'm pioneering AI-driven enterprise automation that transforms how large organizations operate. Currently at AT&T, I'm building systems that learn from human experts and autonomously execute complex workflows — turning what once took hours into automated processes that complete in minutes.

My work centers on multi-agent AI systems powered by LangGraph orchestration, Retrieval-Augmented Generation (RAG), and vector databases. When a domain expert records a workflow, my systems analyze it, generate semantic embeddings, and store it as reusable intelligence.

With deep expertise in production ML systems, GPU optimization, and distributed computing, I build scalable AI solutions that deliver measurable enterprise impact at the intersection of cutting-edge research and real-world deployment.

02 — Experience

Professional history

01 / 04

AT&T AI Foundry

GenAI Engineer

  • $47Mcombined savings per year
  • $20MAI BDR, savings per year
  • $23MCollections Intelligence, savings per year
  • $4MCustomer Insights Agent, savings per year
  • Built production-grade GenAI systems spanning enterprise workflow automation and schema-aware NL-to-SQL intelligence for internal business users.
  • Designed LangGraph orchestration, dynamic tool binding, human gating, evaluation pipelines, and failure recovery for real enterprise workflows.
  • Shipped systems with async control flow, observability, and business-facing outputs over internal tools, PostgreSQL metadata, and Snowflake data.
  • Delivered an agentic outbound-sales platform (AI BDR) and an explainable collections decisioning engine alongside the agent platform and the Customer Insights Agent.
02 / 04

Microsoft

Automation Engineer

  • 99.92%availability, multi-agent framework on AKS
  • ~2×throughput, GPU model serving
  • 69→92%citation pass rate with hybrid retrieval
  • Architected event-driven multi-agent framework on AKS with LangGraph + Azure Functions — 99.92% availability.
  • Deployed GPU model serving with Triton + vLLM: ~2× throughput, 35–50% lower cost/1k tokens.
  • Built hybrid retrieval system; citation pass rate from 69% → 92%, unsupported answers down 30%.

03 / 04

Optum

AI Engineer

  • ~20%faster target discovery
  • Built HIPAA/GDPR-compliant drug-discovery platform unifying PDB/ChEMBL/PubChem, TCGA/GEO, ClinicalTrials.gov.
  • Accelerated target discovery ~20% using AlphaFold-style structural features with genomic Transformers.
  • GraphSAGE/GAT + BioBERT/Med7 for trial recruitment; sub-second updates via Kafka + Flink.

04 / 04

Quora

Machine Learning Engineer

  • Production recommender stack: two-stage ANN retrieval (FAISS/Pinecone) + learned ranking.
  • Real-time feature pipelines at scale — Kafka/Flink with online/offline feature store parity.
  • Multi-task learning optimizing CTR, read time, quality, and fairness simultaneously.

03 — Work

Selected systems & projects

Systems — AT&T

01 — Enterprise agent platform

AI Agentic Foundry

Production-grade multi-agent orchestration platform that automates enterprise workflows with stateful execution, tool calling, human-in-the-loop gating, and self-healing remediation.

  • 85+ workflows
  • interrupt / resume
  • async gates

Problem

Enterprise workflows are multi-step, non-deterministic, dependent on multiple systems, and prone to failures from bad inputs, API issues, or approval requirements. Rule-based automation breaks quickly on these edge cases.

Solution

A LangGraph-based 7-stage pipeline that decomposes requests into specialized agent responsibilities, isolates context, binds tools dynamically, pauses for approvals, and resumes after human or system events.

Architecture — 7 stages

  1. Retrieval
  2. Planningdecompose into agent responsibilities
  3. Validation
  4. Executiontools bound at runtime via /v1/tools
  5. Remediationcorrective action, not a naive retry
  6. Gateshuman · timed · system
  7. Summary

Highlights

  • Dynamic tool registry with runtime discovery via /v1/tools, category-based routing, and tighter execution accuracy.
  • Error remediation agent captures failed step context, tool responses, and error messages to generate corrective actions instead of naive retries.
  • Human, timed, and system gates implemented with LangGraph interrupt/resume patterns and Azure Durable Functions.

Impact

  • Enabled automation across multiple enterprise workflows with production-grade async orchestration.
  • Reduced manual intervention through self-healing execution and approval-aware control flow.
  • Improved determinism with context isolation, tool binding, and structured stage transitions.

Stack

Python, FastAPI, LangGraph, LangChain, OpenAI / Azure OpenAI, PostgreSQL, ChromaDB, Docker, AKS, LangSmith

02 — Enterprise data intelligence

Customer Insights Agent (CIA)

Natural-language intelligence layer over enterprise Snowflake data that lets business users query complex datasets without writing SQL, while still returning structured, business-ready answers.

$4Msavings per year

  • 23+ tables
  • schema-aware RAG
  • 85+ golden cases

Problem

Business users do not know SQL, schema design, or join logic, while enterprise data is spread across 23+ related tables with non-trivial relationships and domain-specific business rules.

Solution

A LangGraph NL-to-SQL pipeline that retrieves schema context, resolves joins dynamically, triages unsupported requests, routes to an Ask Data API for SQL generation and execution, and summarizes the output for non-technical users.

Architecture — 9 stages

  1. Setup
  2. Intent
  3. Table RAGpgvector + HNSW over table metadata
  4. Dataset Select
  5. Triageanswerability gate before SQL cost
  6. Enrichmentjoins on CUSTOMER_KEY · FAN_ID · ACCT_ID
  7. SQL + ExecuteAsk Data API
  8. Summarybusiness-ready answer
  9. Persist

Highlights

  • Schema-aware RAG over table metadata using pgvector with HNSW indexing for fast retrieval of relevant tables.
  • ER relationship model for keys like CUSTOMER_KEY, FAN_ID, and ACCT_ID to support multi-table reasoning.
  • Answerability gate catches unsupported or missing-data scenarios before wasting cost on downstream SQL generation.
  • Five-stage evaluation system with 85+ golden cases, per-table analysis, and LLM-as-judge scoring for SQL and answer quality.

Impact

  • Enabled non-technical users to query enterprise data without depending on analysts for every question.
  • Improved SQL reliability through schema retrieval, join modeling, and structured evaluation loops.
  • Scaled the system across multiple business domains with a cleaner separation between orchestration and execution.

Stack

Python, FastAPI, LangGraph, PostgreSQL, pgvector, Snowflake, LiteLLM, Azure OpenAI, Ragas, Docker

03 — Agentic sales automation

AI BDR

Event-driven, multi-agent sales-development platform that automates outbound prospect journeys across email and voice, with a durable state machine for every prospect.

$20Msavings per year

  • email + voice journeys
  • durable state machine
  • human handoff

What it does

Instead of behaving like a traditional chatbot, the platform maintains a durable state machine for every prospect. AI agents generate outreach, evaluate content quality, classify replies, select the next best channel and call-to-action, adapt cadence, and determine when an opportunity should be handed off to a human seller.

Architecture

A FastAPI service layer with asynchronous workers, PostgreSQL-backed state and queues, specialized LLM agents, communication integrations, and durable workflow controls. Every state transition is validated and persisted.

Prospect / Campaign → API → Dispatch Queue → Worker → Campaign Orchestrator → Specialized LLM Agents → State Machine → Email / Voice / Meeting Tools → Reply Classification → Next Best Action → Seller Handoff

Journey lifecycle — 5 phases

  1. Pre-touch
  2. Execution
  3. Classification
  4. Routing
  5. Audit

The agentic system

  • Multi-agent decisioning: specialized agents for content generation, reply classification, quality evaluation, seller briefing, voice interaction, CTA and channel selection, cadence adaptation, and unified cadence policy.
  • Durable orchestration: a typed state machine with guarded phase transitions, not stateless prompt chains.
  • Event-driven execution: campaign touches are queued and processed asynchronously by worker and orchestrator components with persisted journey state.
  • Human-in-the-loop: escalation and seller handoff are part of the prospect journey, not an afterthought.
  • Multichannel delivery: email, inbound reply monitoring, voice workflows, meeting scheduling, and webhook-driven external events.

Reliability, safety & delivery

  • PostgreSQL work queues using SKIP LOCKED, leases, retry and backoff, dead-letter handling, optimistic locking, a transactional outbox, idempotency keys, checkpoints, and deterministic LLM fallbacks.
  • PII scanning, delivery allowlists, calling-window controls, signed integration requests, authenticated access, and pre-delivery validation.
  • Containerized and deployed to Azure Kubernetes Service with Helm and Azure DevOps CI/CD: automated linting, unit testing, quality gates, image publishing, and deployment pipelines.
  • 64 unit tests, 28 integration tests, and 26 scenario-based test flows, plus dedicated LLM evaluation workflows.

Stack

Python 3.11, FastAPI, Pydantic, PostgreSQL, async psycopg, GPT-4o, LiteLLM, React, Azure Kubernetes Service, Docker, Helm, Azure DevOps, SMTP/IMAP, voice APIs, webhook integrations, Entra/JWT authentication

04 — Risk intelligence & decision automation

Collections Intelligence

Explainable collections decisioning platform that scores B2B accounts, selects a policy-aware next best action, and prioritizes collector worklists.

$23Mcombined savings per year

$15Mproactive risk assessment

$8Mintelligent payment reminders

  • explainable scoring
  • next best action
  • closed feedback loop

What it does

Consolidates account, billing, payment, dispute, credit-risk, autopay, and collections-feedback data into a canonical customer profile. It derives decision features, evaluates deterministic risk and policy rules, generates a recommended treatment action, ranks accounts by business priority, persists results, and feeds downstream collections workflows.

Explainable by design

Unlike a simple reminder scheduler, every recommendation carries its contributing risk drivers and matched business rules. Missing information is treated explicitly as unknown rather than zero, repeated treatments are suppressed, and policies vary by account segment and plan family.

Pipeline — 9 stages

  1. Enterprise databilling, aging, payments, disputes, credit risk, autopay
  2. Canonical profileone contract regardless of source
  3. Derived featuresmissing data stays unknown, never zero
  4. Risk scoringdeterministic, rules-based
  5. Next best actionindependent of the risk score
  6. Priority rankingrisk · exposure · urgency · account value
  7. Persistence
  8. Collections worklist
  9. Feedback loopoutcomes feed the next evaluation

The decision engine

  • Designed a canonical collections-domain model that isolates upstream data complexity from downstream scoring and decision logic.
  • Built a feature-engineering layer for delinquency, payment behavior, credit risk, account status, treatment eligibility, and collections history while preserving explicit missing-data semantics.
  • Implemented an explainable rules-based risk scoring engine that combines delinquency severity, amount at risk, urgency, customer value, and treatment context into deterministic account-level assessments.
  • Designed a policy-driven Next-Best-Action engine that evaluates account state independently and selects the collections treatment through configurable decision paths, separating risk estimation from treatment selection.
  • Segment-aware policy routing with distinct treatment strategies for enterprise, public-sector, and SMB account families, and safe fallback paths for unsupported configurations.
  • Suppression and treatment-history controls prevent duplicate or repetitive recommendations.
  • Batch pipeline evaluates accounts nightly or on demand, persists account-level decisions, and incorporates representative feedback into subsequent runs.

KPIs it was designed around

  • Reducing roll rates into deeper delinquency and detecting high-risk accounts earlier.
  • Reducing total amount at risk.
  • Improving treatment acceptance, promise-to-pay fulfillment, and prioritized worklist adoption.

Stack

Python, FastAPI, PostgreSQL, Snowflake, rule engines, feature engineering, batch processing

Projects

Custom Transformer Training Pipeline

  • Transformer LM from scratch in PyTorch
  • DDP across multiple GPUs
  • Custom data preprocessing pipeline

GPU Kernel Optimization Framework

  • nvprof + Nsight profiling
  • Custom CUDA kernels
  • 25% inference latency reduction

Multi-Agent Automation System

  • LangGraph event-driven pipeline
  • Saga pattern
  • 99.92% availability
  • Autonomous remediation

Hybrid RAG Retrieval System

  • Azure AI Search + FAISS
  • 92% citation accuracy
  • NLI hallucination guardrails

04 — Research

Research & stack

While everyone scales parameters, I'm optimizing what the model chooses to forget.

72.4% memory reduction, 99% accuracy retained

BudgetMem: Selective Memory Policies for Cost-Efficient Long-Context Processing

  • 72.4% memory reduction, 99% accuracy retained (1% F1 drop) on long-document benchmarks.
  • Validated on $10/month hardware (Google Colab) — democratizes long-context AI without GPU infrastructure.

Low-Level GPU Profiling & Kernel Debugging

  • Profiling playbook: nvprof, Nsight Systems/Compute, NCCL traces — warp divergence, uncoalesced memory, launch overhead.
  • Kernel fusion, shared-mem tiling, async copy, CUDA Graphs → double-digit latency reductions on inference workloads.

Automation Pipelines

  • Event-driven multi-agent pipeline with sagas, retries, idempotent checkpoints — hours to minutes.
  • Offline eval harness (pass@k, citation correctness, hallucination rate); SME prep time cut ~60%.

Stack

Models / trainingPython, PyTorch, TensorFlow, Keras, Hugging Face, CUDA, vLLM.

Agents / retrievalLangGraph, LangChain, LlamaIndex, LiteLLM, RAG, Guardrails AI, MCP.

Data / vectorsQdrant, FAISS, Pinecone, ChromaDB, PostgreSQL, Redis, Kafka.

PlatformAzure, AWS, Docker, MLflow, Git.

LanguagesPython, Go, C++, Java.

05 — Contact

Portrait of Chandra Alla

If your agents need to survive production,

Let's talk.

Building agents, or trying to cut what your models cost to run? I'd like to hear about it.

chandraalla72@gmail.com